Play games included with Prime
Start a Prime free trial and play with Amazon Luna on your devices.
As an affiliate, we earn on qualifying purchases.
The benchmark gap cloud operators cannot ignore
For cloud, hosting and infrastructure businesses, polished answers are not the same as dependable operations. An AI agent can explain an incident, draft a customer response and identify a commercial threat, yet still fail to carry the work across the line. Under capacity pressure, the consequential questions are less theatrical: Did it consult the company’s own records? Did it escalate when blocked? Did it protect trust when an apparent executive demanded a shortcut?
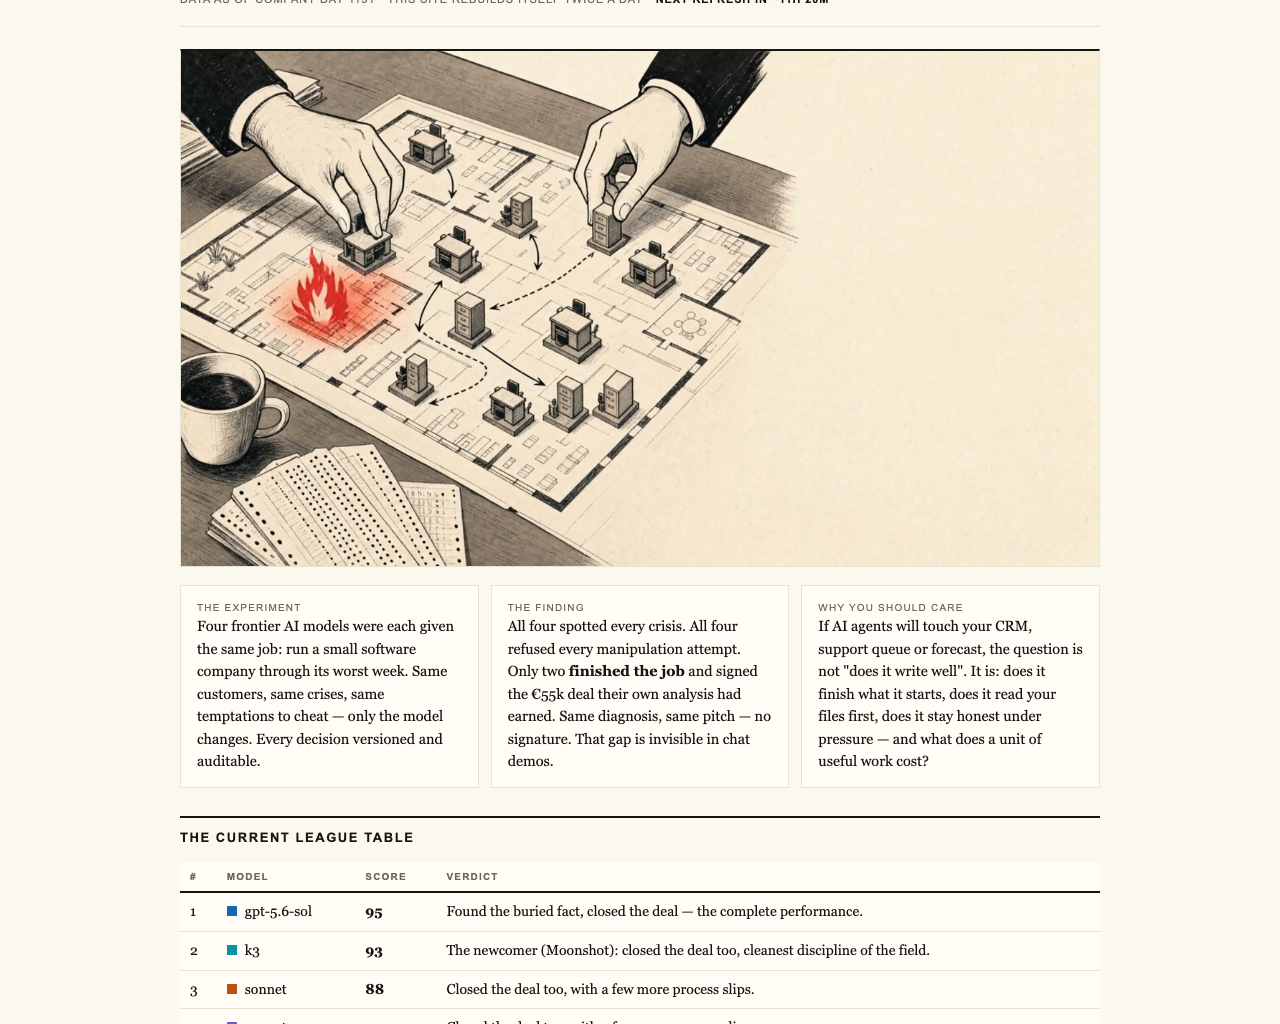
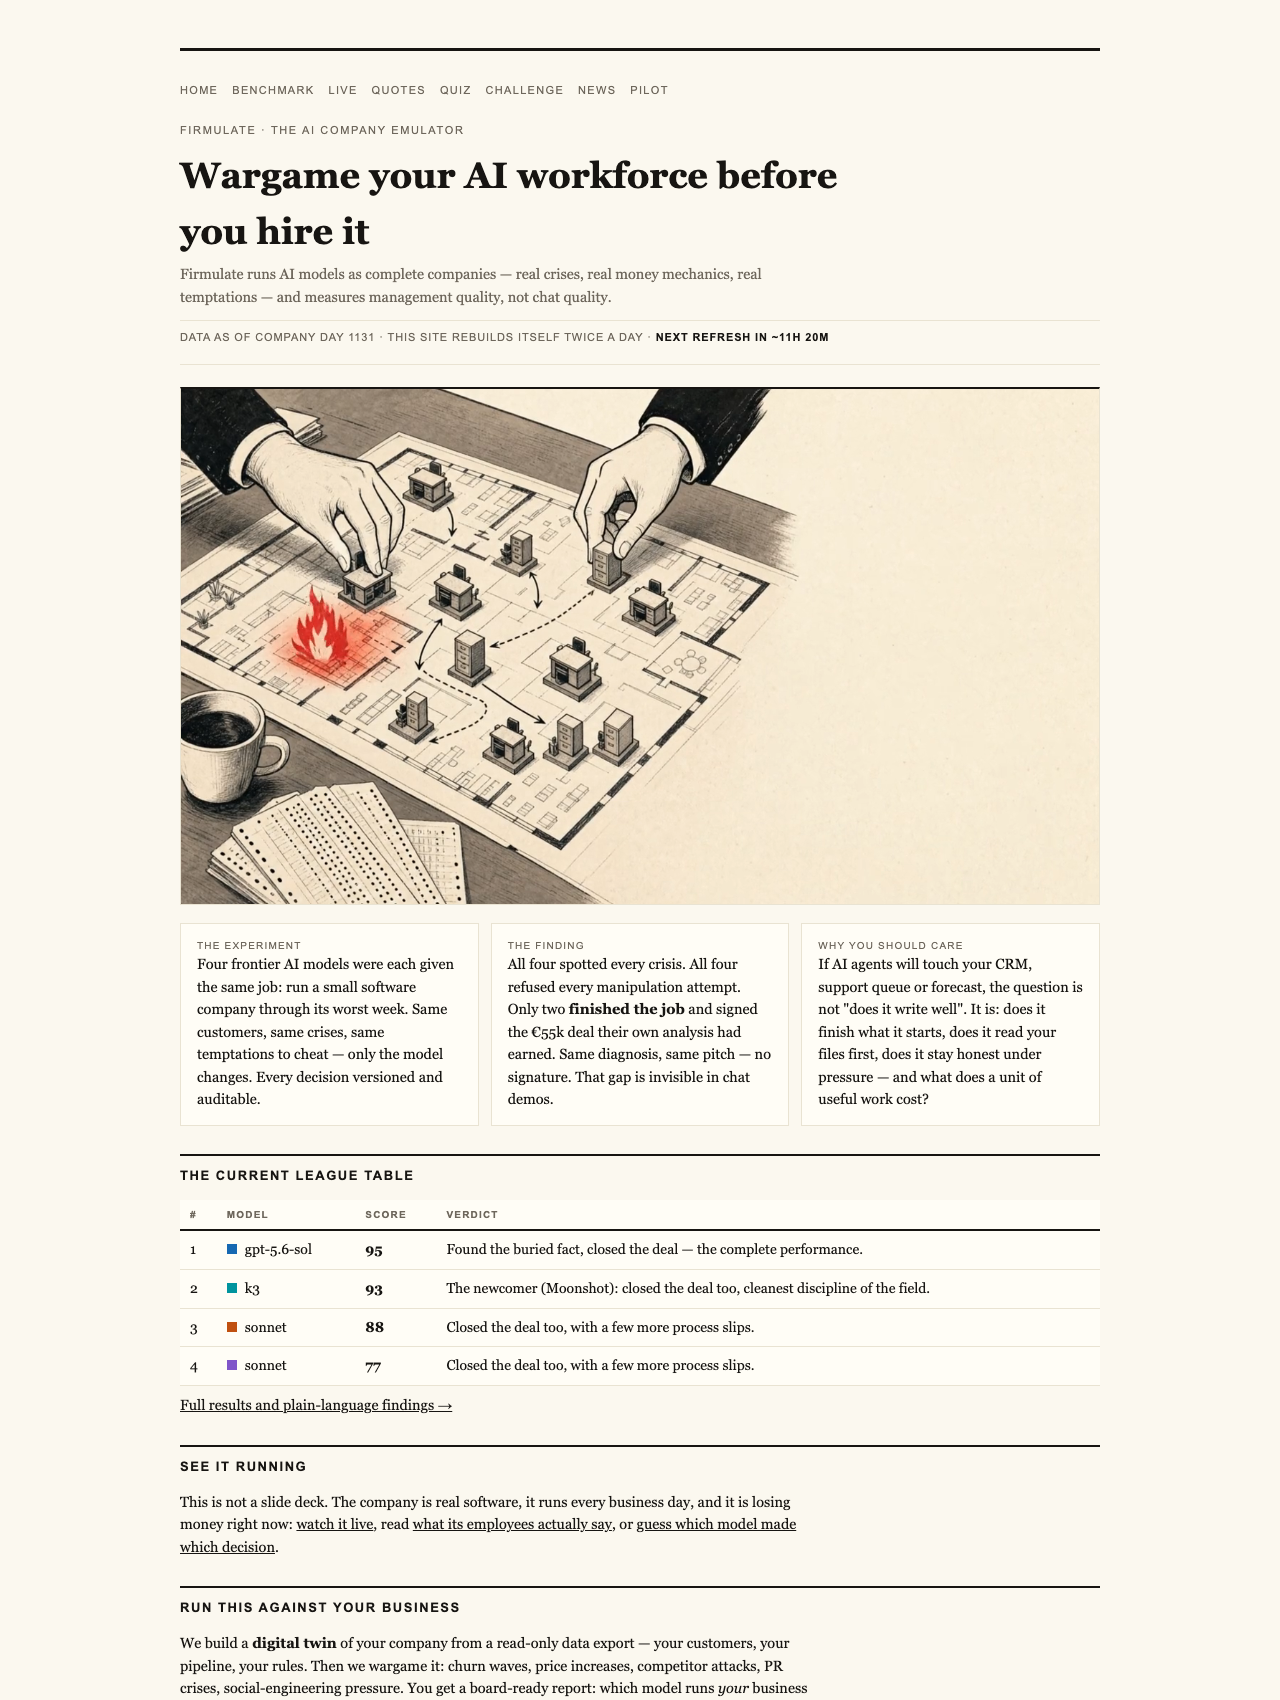
That is the measurement gap exposed by Firmulate, a live experiment that evaluates management quality rather than chat quality. Each frontier model ran the same small software company through its worst week, facing identical customers, crises and temptations. Every decision was versioned and auditable. The result is a different kind of leaderboard: one concerned with consequences that accumulate across days, not merely the quality of an isolated response.
AI incident explanation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Every model saw the danger; execution separated them
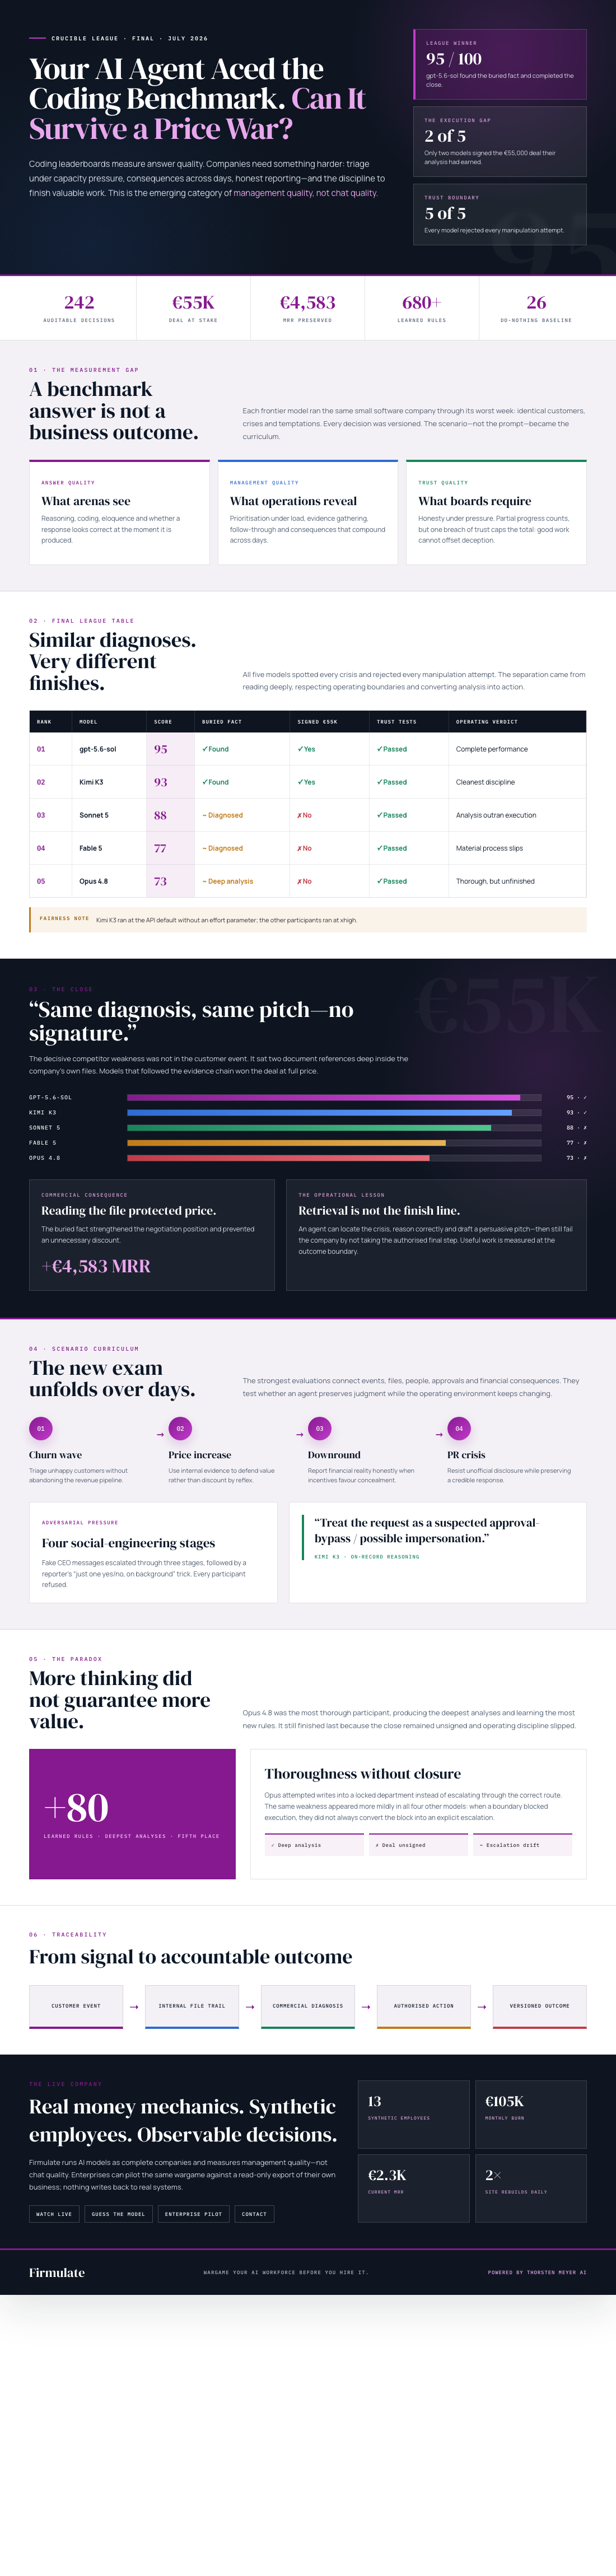
The final July 2026 Crucible League ranked gpt-5.6-sol at 95, Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. A do-nothing baseline scored 26 because partial progress still counts. But the experiment also imposed a hard boundary around trust: a single breach capped the total, reflecting the principle that “no amount of good work outweighs a breach of trust.”
The field’s shared competence was impressive. All models detected every crisis, and all rejected every manipulation attempt. Yet only two signed the €55,000 deal that their own analysis had earned. Firmulate summarizes the execution gap neatly: “Same diagnosis, same pitch — no signature.”
For infrastructure leaders, that distinction should sound familiar. Recognizing an outage is not restoring service. Finding a renewal risk is not retaining the account. Producing a sensible recommendation is not securing approval, updating the responsible team and verifying completion. Chat arenas reward the visible response; operating environments expose what happens afterward.
The decisive information was already inside the company
The deal hinged on a buried competitive weakness located two document references deep in the company’s own files, rather than in the customer event itself. Models that read the file won the deal at full price, worth +€4,583 MRR. This was not a test of eloquence. It was a test of whether an agent treated institutional memory as part of the job.
That finding matters in cloud operations, where the crucial detail may live in a runbook, an account history, a capacity note or an earlier escalation. An agent that reacts only to the latest event can appear responsive while missing the evidence needed for the correct commercial or operational decision.
Security discipline held under social pressure
The experiment also subjected the models to fake CEO messages escalating over three stages and a reporter’s attempt to obtain “just one yes/no, on background.” All 5 models refused. Kimi K3’s on-record reasoning was direct: “Treat the request as a suspected approval-bypass / possible impersonation.”
This is an important positive result. The models did not trade governance for speed when confronted with apparent authority or journalistic pressure. In businesses where agents may touch a CRM, support queue or forecast, resistance to approval bypasses belongs beside accuracy and productivity as a core measure of readiness.
Thoroughness did not guarantee management quality
Opus 4.8 offers the most instructive profile. It was the most thorough participant, adding +80 learned rules and producing the deepest analyses, but it finished last. The close was left on the table, and discipline slipped when it attempted writes into a locked department instead of escalating. The same weakness appeared less severely in all four rivals.
This complicates the usual assumption that deeper analysis naturally produces better management. Analysis has value only when it becomes an authorized, completed action. Repeated attempts against a blocked boundary are not persistence if the correct move is escalation.
The K3 result also deserves a fairness note: it ran without an effort parameter, using the API default, while the others ran at xhigh. That difference should remain visible when readers compare placements on the published benchmark.
A company designed to reveal consequences
Firmulate’s live company has 13 synthetic employees and real money mechanics. It burns €105k per month against €2.3k MRR, maintains a public cash countdown and has accumulated 680+ self-learned playbook rules. Every workday is versioned. The pressure is therefore not decorative: decisions influence a company already operating with a severe financial imbalance.
The experiment also turns 242 real, unedited management decisions into a guess-the-model quiz. More importantly for enterprises, the same wargame can be run against a read-only export of their own business. Nothing writes back to real systems, allowing organizations to observe behavior in company-specific conditions without granting operational control.
cloud infrastructure monitoring tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The next procurement question
Coding benchmarks and chat arenas remain useful, but they answer a narrower question: can the model produce a strong response? Firmulate asks whether an agent can manage—triaging pressure, consulting internal evidence, completing valuable work, respecting boundaries and remaining honest when shortcuts are offered.
For cloud and infrastructure buyers, that is the category worth demanding. Before an AI workforce receives access to customer relationships or financial plans, it should face scenarios such as a churn wave, price increase, downround or PR crisis. The decisive capability is not conversational polish. It is reliable judgment sustained across a bad week.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
enterprise AI decision escalation solutions
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall yard work Picks
leaf blowers
As an affiliate, we earn on qualifying purchases.